Models·EASYHUB JOURNAL
Liquid AI launches d1, a text-and-vision decision model that returns probabilities in one forward pass without generating output tokens
What changed
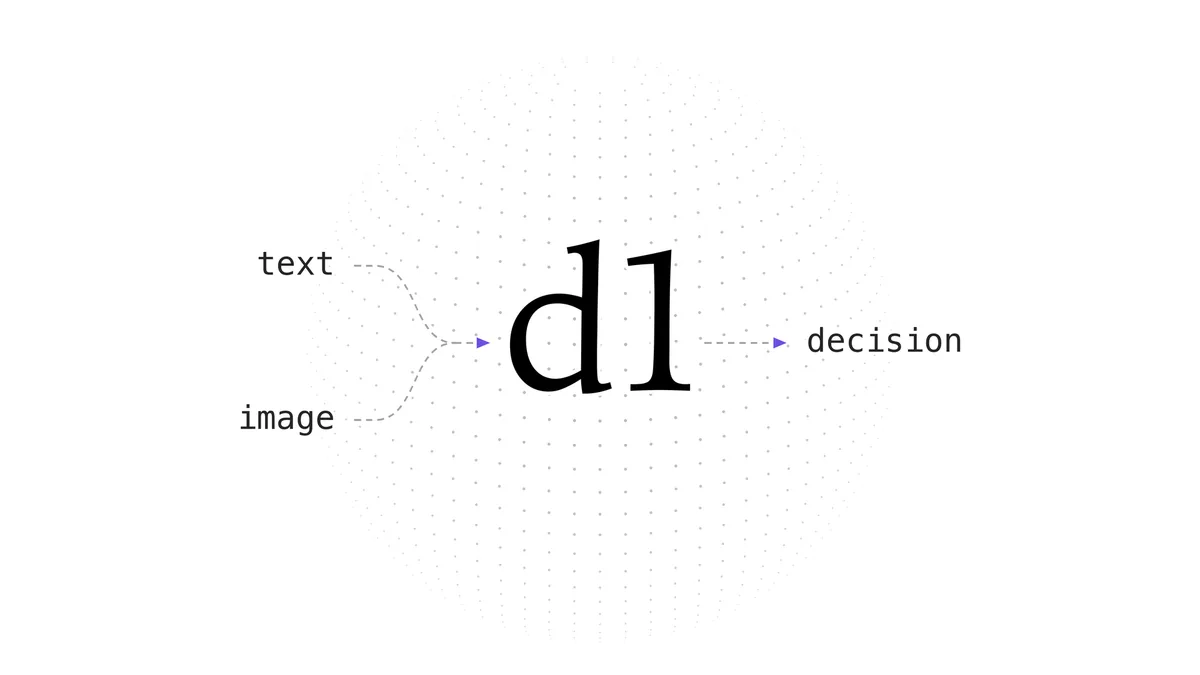
Liquid AI formally launched d1 on October 5 as its first decision model supporting both text and images. Instead of generating free-form output tokens, d1 reads unstructured input plus one or more questions in a single forward pass and returns probabilities for yes/no, choice or score decisions; Liquid says text decisions typically take 200–300 ms. The model is available through the Liquid API for tasks such as visual inspection, filtering, code search, agent action selection and context compaction. Liquid reports that d1 matched or beat GPT-6.1 Sol on four of six internal applications and claimed 19–200x lower cost; those figures are vendor-run measurements rather than independent rankings.
- Original title
- Introducing d1: The most capable decision model, now with vision
- Source
- Liquid AI · www.liquid.ai
- Topic
- Models
- Source month
- 2026-10
This is a concise EasyHub summary of the linked source, not the full report or original reporting. Availability and preview conditions are described in the summary and original.
Summary page published · Editorial information