
Compact models·EASYHUB JOURNAL
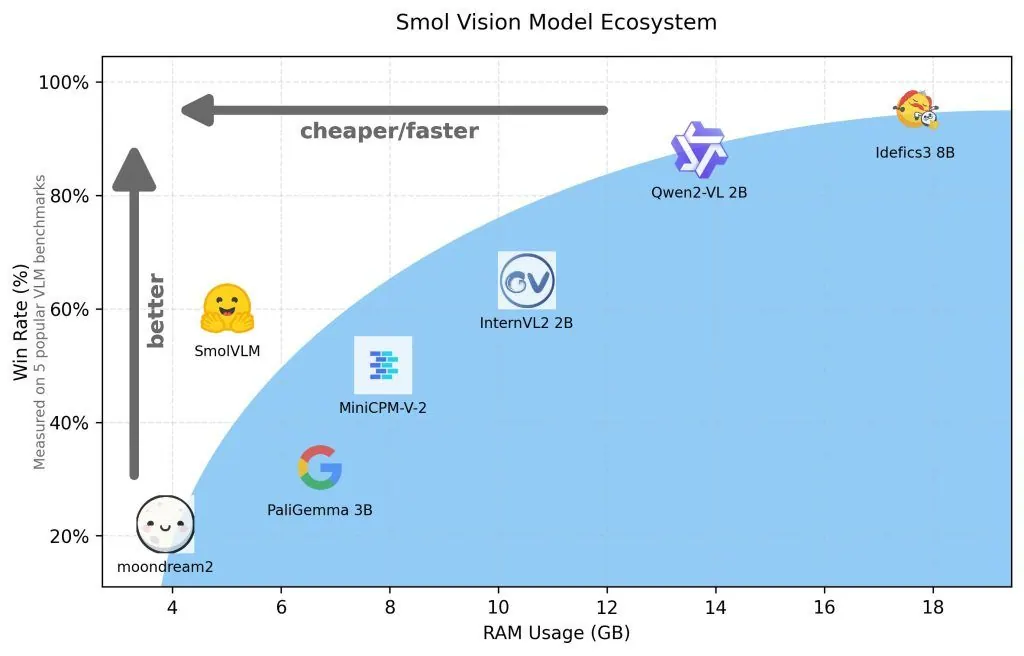
SmolVLM targets low-memory visual-language inference at 2B parameters
What changed
SmolVLM reduces visual-language inference costs with a compact backbone and compressed image representations. Base and tuned variants accompany open training assets, offering a smaller starting point for device-specific experimentation and fine-tuning.
- Original title
- Hugging Face 发布 SmolVLM 开源 AI 模型:20 亿参数,用于端侧推理,体积小、速度快
- Source
- IT之家 · www.ithome.com
- Topic
- Compact models
- Source month
- 2024-11
This is a concise EasyHub summary of the linked source, not the full report or original reporting. Availability and preview conditions are described in the summary and original.
Summary page published · Editorial information