
Speech and audio·EASYHUB JOURNAL
Qwen3-ASR separates recognition and timestamp alignment components
What changed
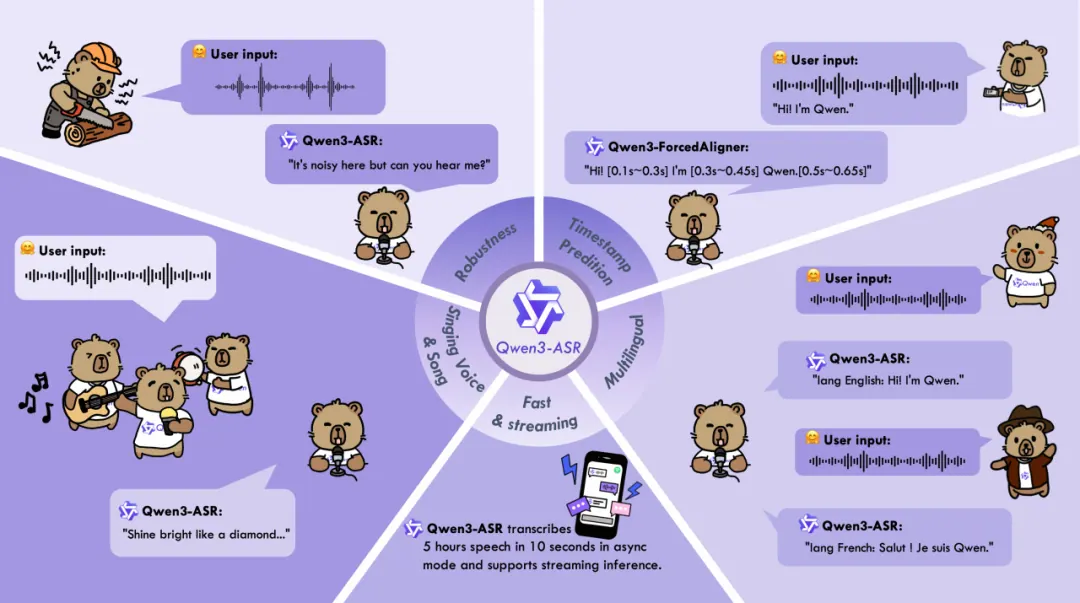
The release combines two recognition sizes with a separate forced aligner and streaming tooling. Language coverage, batch throughput and single-request latency measure different things and need separate deployment checks.
- Original title
- 阿里千问开源 Qwen3-ASR 语音识别模型:支持 52 种语种与方言,1.7B 版本达 SOTA 水平
- Source
- IT之家 · www.ithome.com
- Topic
- Speech and audio
- Source month
- 2026-01
This is a concise EasyHub summary of the linked source, not the full report or original reporting. Availability and preview conditions are described in the summary and original.
Summary page published · Editorial information