
Compact models·EASYHUB JOURNAL
HY-1.8B-2Bit uses quantization-aware training for smaller deployments
What changed
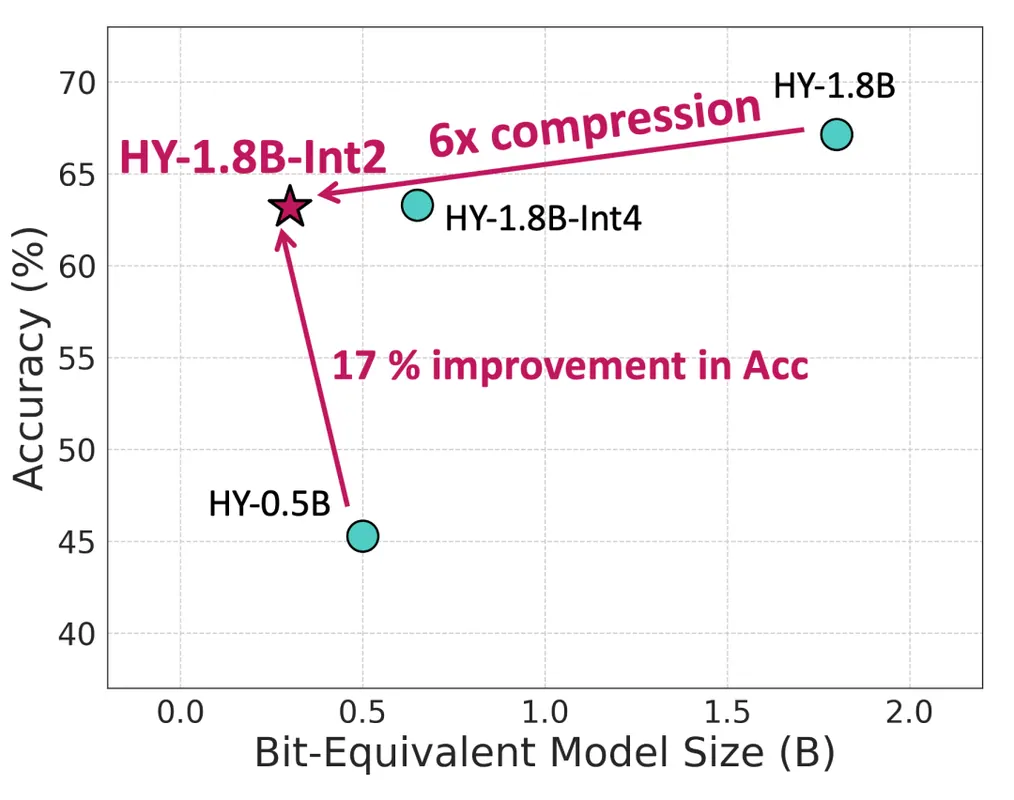
HY-1.8B-2Bit uses quantization-aware training on a 1.8B model, with low-bit GGUF and BF16 fake-quantized weights while retaining reasoning modes. Tencent reports roughly 300MB of weights and 600MB memory in its runtime configuration. Quantization does not change the underlying parameter count to 0.3B.
- Original title
- 腾讯混元推出 0.3B 端侧模型,内存占用仅 600MB
- Source
- IT之家 · www.ithome.com
- Topic
- Compact models
- Source month
- 2026-02
This is a concise EasyHub summary of the linked source, not the full report or original reporting. Availability and preview conditions are described in the summary and original.
Summary page published · Editorial information